AI Agents in Finance: What They Can and Cannot Safely Automate in 2026
Picture the 27th of the month. A controller opens the shared inbox and finds 140 vendor invoices, a bank feed with three weeks of unmatched lines, and a message from the owner asking whether "the AI thing" can just handle all of it. (This is an illustration, not a case study.)
The honest answer has three parts. Some of it can be automated safely today. Some of it works only as a drafting assistant, with a person approving every step. And some of it should not run without a named human making the call. The hard part is not knowing that these categories exist. The hard part is knowing which task belongs in which one before something goes wrong with real money.
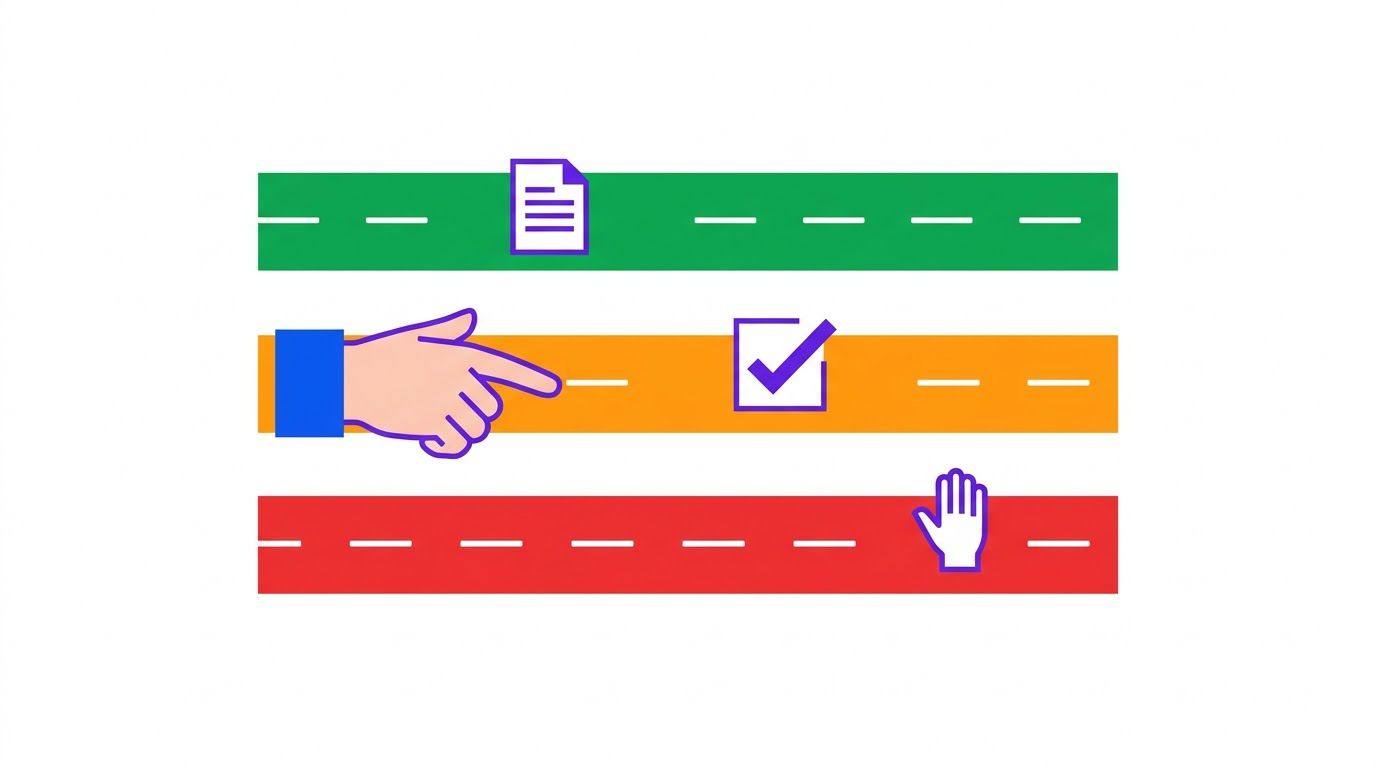
This guide gives you a capability boundary map: 18 finance tasks sorted into a green zone (reliable with light checks), an orange zone (the agent prepares, a person decides) and a red zone (a human owns the decision). You also get the four-question test to sort your own tasks, the controls that keep a person in the loop without grinding everything to a halt, and the metrics that tell you an agent has started to drift.
One note on what this is. It is a framework, not a lab report. It is built from public sources (listed at the end, each with the date we checked it), from standard internal-control ideas such as segregation of duties and maker-checker review, and from how these tasks are structured. We did not run experiments for it, and every number inside a worked example is a made-up illustration, labeled as one. Treat each threshold as a starting point to calibrate on your own data. This is general information, not legal, tax or financial advice.
- Adoption is early. In FirstPageSage’s 2026 data, 13% of small businesses had deployed at least one agentic AI system, and most of those were still experimenting.
- Green zone: the agent reads, sorts, drafts or flags, and a mistake costs minutes. Examples: invoice data extraction, document classification, suggested bank matches, report assembly.
- Orange zone: money, relationships or the ledger move. The agent prepares and a person approves. Examples: approvals, payment runs, forecasts, collections emails, journal entry proposals.
- Red zone: a law, a contract or the books of record require a named human. Examples: credit decisions, fraud conclusions, unreviewed postings, tax filings.
- The real skill is architecture: confidence thresholds, exception queues, dollar caps, sampling and drift metrics. That is what turns an agent from a demo into something you can leave running.
- Where AI agents in finance really stand in 2026
- The four-question test for sorting any finance task
- Green zone: six tasks an agent can run with light checks
- Orange zone: six tasks where the agent prepares and you decide
- Red zone: six tasks a human must own
- The full capability boundary map
- Score your own tasks: worksheet and net-hours formula
- How to build human-in-the-loop without killing productivity
- Signals that a finance agent is drifting
- What to automate first: a 30-day sequence
- When it is time to hand it to someone
- Frequently asked questions
- Sources
Where AI agents in finance really stand in 2026
Most writing about AI agents swings between "they will replace your finance team" and "they do not work." Neither helps you decide what to do on Monday. The public data points to something more useful: adoption is real but early, most projects are still in the experiment stage, and a meaningful share of teams that try agents stop.
Read the numbers carefully
Three details change how you should use these figures.
- "Adoption" is a low bar. FirstPageSage counts a company as an adopter if it has deployed at least one agentic AI system in any capacity. A pilot in one department qualifies. So the 13% tells you how many small businesses have touched agents, not how many have handed them real finance work.
- The 79% applies to adopters only. It is the share of small businesses that already adopted agents and are still in the experimentation stage. It is not 79% of all small businesses. The same table puts only 5% of SMB adopters at "fully deployed" and 3% at "fully deployed at scale."
- The methodology is thin. The report says it compiles research and industry surveys covering more than 15,000 businesses, but it does not give sample sizes by segment or say which source feeds which table. Use the figures as a directional signal, not as a benchmark you quote to a board.
The Retool number needs the same care. Retool surveyed 307 senior technology and security leaders in May 2026 at companies with 50 or more employees. 22% reported at least one production incident caused by an AI-generated internal tool (19% once, 3% more than once), and another 51% said they could not say for certain. Only 8% described their AI governance as strong. That survey is about internally built AI tools in general, not finance agents specifically. It still shows what happens when tools ship faster than the controls around them.
Forrester’s June 2026 write-up on agentic AI lands in the same place from the enterprise side. Roughly three-quarters of enterprise leaders say they are adopting agentic AI, yet the piece describes only a small minority as running agents in meaningful production.
You may have come across the claim that 88% of AI agent pilots never reach production, often credited to Forrester. We could not find that number in Forrester’s own published material, so we do not use it. When a statistic arrives without a primary source, the safest move is to leave it out.
Why finance projects stall
The public data does not explain why 43% of small-business agent efforts get cancelled, so what follows is reasoning from how these projects are structured, not a finding. Four causes are likely:
- The scope is too wide. "Automate accounts payable" is not a task. It is a department. Projects that start there never reach a testable definition of done.
- There is no exception path. Every real invoice stream contains weird documents. If the design has no place for them to go, a person ends up doing the work on the side, and trust in the agent erodes.
- Nobody owns review. An agent that produces drafts nobody checks is an uncontrolled process with a friendly interface.
- Success is never measured. Without a baseline (minutes per invoice, error rate, exceptions per week), nobody can tell a good month from a bad one, and the project drifts until someone cancels it.
Finance is also unforgiving in a specific way: errors are quantifiable and auditable. A wrong sentence in a marketing draft is an edit. A wrong digit in a payment is a recovery process. That is why a map of safe and unsafe zones is worth drawing before you write a single prompt.
The four-question test for sorting any finance task
Before looking at the 18 tasks, you need a method you can apply to the 19th. Ask four questions about any task, in this order.
- Can the result be undone in minutes, without anyone outside your team noticing? (Reversibility.) A wrongly classified document can be re-sorted. A payment that left the bank cannot be recalled by editing a cell.
- Does the output move money or change a book of record? (Movement.) Drafts and flags do not. Payments, postings and master-data changes do.
- Does a law, a contract or a policy require a named person to make or explain the decision? (Duty to explain.) Credit decisions, tax positions and sign-offs usually do.
- Can a person check the result faster than doing the task from scratch? (Verifiability.) If checking costs as much as doing, the agent is not saving you anything yet.
| If your answers are… | Then the task is… | What it means |
|---|---|---|
| Undoable, no movement, no duty to explain, easy to verify | Green zone | The agent can run it, with sampled review and rules checks. |
| Hard to undo, or it moves money or the books, but no legal duty to explain | Orange zone | The agent prepares. A person with authority approves before anything moves. |
| A named person must make or explain the decision | Red zone | A human owns it. The agent can gather evidence and draft a memo, never decide. |
| Checking takes as long as doing | Red zone | Do not automate yet. Fix the process, then retest. |
Agent or workflow? Use the cheaper tool where the logic is clear
"AI agent" has become a catch-all label, and it hides a design choice that matters in finance. Many of the tasks below are best built as a workflow with one AI step inside it, not as a free-roaming agent. The AI handles the messy part (reading a crooked PDF, interpreting a free-text email). Fixed rules handle the parts where the logic is clear: if the amount is above a threshold, route to a second approver; if the vendor is new, hold for review; if the lines do not sum to the total, reject.
Rules are cheaper to run, easier to audit and impossible to talk out of their instructions. A prompt that says "never pay more than $5,000 without approval" is a request. A rule in the workflow that blocks the step is a control. Wherever you can express the decision as a rule, express it as a rule and keep the model for what only a model can do.
That design is also why this kind of automation fits a tool like n8n (may be an affiliate link): a visual workflow shows every step, every branch and every place a person is asked to approve, so a controller can read it like a process map. At LeenLabs, that is the kind of workflow we build for people who want automation they can inspect. If you already know which task on the map is yours, you can describe it on our Request a Custom Workflow page and get a quote. If you are not sure yet, keep reading. The next three sections will help you decide.
Green zone: six tasks an agent can run with light checks
What the six green tasks have in common is a shape: the agent reads, sorts, drafts or flags, and the cost of a mistake is a few minutes of someone’s time. None of them moves money, none of them posts to the ledger on its own, and each one has a cheap, automatic way to catch errors. "Green" does not mean "unsupervised." It means the supervision can be rules and sampling instead of a person approving every item.
Extraction is a good first task for an agent, and the reason is structural. The output is a draft that gets verified by rules before it goes anywhere. If the model misreads a total, the arithmetic check fails and the invoice lands in review. The model does not need to be perfect. The system around it needs to be strict.
If you want to see the pattern in practice, our free workflow Extract Invoice Data from PDFs with n8n and Claude walks through an extraction workflow you can import and adapt. Read it with the rules above in mind and look for where the checks would go. Use the article itself for what it covers and what it needs, and add your own validation steps before anything reaches your accounting system.
The numbers below are invented to show how routing works. They are not results from any real system.
| Invoice | Total | Lowest field confidence | Checks passed? | Route |
|---|---|---|---|---|
| A-1041 | $412.50 | 98% | Yes | Auto-accept to draft queue |
| A-1042 | $1,980.00 | 91% | Yes | Auto-accept to draft queue |
| A-1043 | $7,250.00 | 96% | Yes | Review: above $5,000 review threshold |
| A-1044 | $318.75 | 62% | Lines do not sum to total | Exception queue |
| A-1045 | $640.00 | 97% | Possible duplicate of A-0988 | Exception queue |
Classification is low-risk because misfiling is visible and reversible. A credit note routed as an invoice will usually look wrong in the review queue. The risk lives in the details: a statement mistaken for an invoice can lead to a double payment if nothing downstream checks for duplicates, which is why the duplicate check from task 1 and the flagging in task 6 should always sit behind it.
Reconciliation is a good fit because the evidence is on the page. The agent is not asked to be right about the world, only to line up two lists and explain why. Notice the word "assisted." The agent suggests and a person confirms the ambiguous ones. If you let the agent post the match to the ledger on its own, you have crossed into the orange zone.
The rule that keeps this task green is narrow: facts come from the system, wording comes from the template. The moment the agent starts composing promises or negotiating, the task has become orange or red. Customer-facing collections is a separate task, and it appears in the orange zone for that reason.
Reports are read-only, which is what makes them green. A wrong report wastes time but does not move money. Our free workflow Weekly Accounts Receivable Aging Report with n8n is an example of this kind of task running on a schedule: data in, report out, nothing posted. Check the article for the data sources and setup it uses.
Be strict about the commentary. Let the agent describe what the numbers show ("receivables over 60 days rose from X to Y") and keep the reasons ("because of a customer dispute") for the person who knows the account. A model will happily supply a cause it cannot know.
This is the one green task that gets better with a feedback loop. Every flag a person closes (real or false) is a data point. If 95 out of 100 flags are false alarms, the rule is too loose. If people stop opening them, the rule is too noisy. Log the outcomes from day one.
Extraction, classification and matching all become orange the moment their output posts automatically to your accounting system. The task did not change. The cost of an error did. Keep green tasks writing to a draft queue that a person or a strict rule releases, and you keep the green label.
Orange zone: six tasks where the agent prepares and you decide
Orange tasks are where most of the value and most of the risk sit. Each one moves money, touches a relationship or changes the books, so a person with authority must approve before anything happens. The agent’s job is to make that approval fast and well-informed: gather the facts, check the rules, draft the action, and wait.
Illustrative numbers only. Set your own thresholds with your owner or controller.
| Invoice total | Approval needed | Agent’s role |
|---|---|---|
| Under $500, matched to a PO | Budget owner | Route and remind |
| $500 to $5,000 | Budget owner and finance | Route both, in order |
| Over $5,000 | Budget owner, finance and owner or CEO | Route all three, hold payment until complete |
| Any amount from a new vendor | Finance, plus vendor verification | Hold and flag |
Payments are the clearest case for the orange label. Preparing a batch is tedious and error-prone, which is exactly why an agent helps. Releasing it is irreversible, which is exactly why a person must. Scoped credentials are the simplest guardrail you can add: an agent that cannot release funds cannot be talked into releasing them.
A forecast is a judgment dressed as arithmetic. The agent is excellent at the arithmetic and has no idea what you know about next month. Keep the assumptions visible and keep the person who understands the business in charge of them.
The aging report from task 5 is green. What to do about it is orange. The report only describes; the outreach speaks for your business to a customer. That is a relationship decision, and relationship decisions need a person until you have evidence that the drafts are right.
This is the task most often pushed into the red zone by enthusiasm. An agent that proposes is a time-saver. An agent that posts without review is a risk to your books of record, covered in the red zone below. The difference is a review step that takes a minute per entry.
This sits at the boundary with the red zone. Changed bank details are a classic route for payment fraud, and fraudsters write persuasive emails. An agent can spot that a request changes an account and prepare the paperwork. Confirming that the vendor really asked requires a human on a channel the fraudster does not control.
Describe the task, the tools involved and the point where a person must approve. We reply with a quote to build it as an n8n workflow, or to adapt one of our free workflows to your setup. You pay 40% to start and the remaining 60% on delivery.
Red zone: six tasks a human must own
Red does not mean the agent is useless here. It means the decision stays with a named person. The agent can still gather evidence, draft a memo or prepare a file, but it cannot be the one deciding, and nobody should be able to say "the AI did it" when asked who is accountable.
In the United States, Regulation B (the rule implementing the Equal Credit Opportunity Act) requires a creditor to notify an applicant of the action taken within 30 days of receiving a completed application. An adverse action notice must be in writing and include a statement of specific reasons, or tell the applicant they can ask for one. The reasons must be specific and indicate the principal reasons for the decision. Saying only that the applicant did not reach a qualifying score on your scoring system is not enough under the regulation’s text.
That requirement is hard to meet with a model whose reasoning nobody can state. A 2022 CFPB circular addressed this directly for complex algorithms, but the CFPB’s own guidance page lists it as withdrawn on May 12, 2025. So do not rely on the circular. Rely on the regulation itself and on your counsel. Whether Regulation B applies to you, including to some forms of business credit, is a question for a lawyer. If you extend credit, a person should make and be able to explain every refusal.
Flagging is green. Concluding is red. The same agent can do both jobs, and the label depends on what happens next. If the output is "this looks unusual, please look," it is a flag. If the output is "this is fraud, block it," it is a verdict, and verdicts need an owner.
The risk is not only a wrong entry. It is a ledger that nobody can explain. When an entry is posted by an agent with no review, there is no one to answer the question "why is this here?" A review step takes a minute and creates a person who can answer.
Tax and regulatory rules change, differ by state and country, and depend on facts about your business that are not in the data. Use agents to prepare the file. Have a qualified preparer review and sign. This guide does not give tax advice, and your preparer is the right person to say what applies to you.
This is the most important rule in the whole map. Permissions, thresholds and approval matrices must be set by people and changed by people, in a place the agent cannot write to. Everything else in this guide depends on those limits holding.
Some teams will eventually allow an agent to release small, recurring, pre-approved payments to known payees under a strict cap. That is a decision for your owner or controller, to make deliberately, with a cap, a log and a kill switch. It is never the default.
The full capability boundary map
Here are all 18 tasks in one place. Print it, paste it into your team wiki, or use it as the agenda for a thirty-minute conversation with your controller. Each row names what the agent does, what the person does and the single control that matters most.
| # | Task | Zone | Agent’s role | Human’s role | Key control |
|---|---|---|---|---|---|
| 1 | Extract invoice and receipt data | Green zone | Reads and returns structured fields | Reviews flagged items | Arithmetic and vendor lookup checks |
| 2 | Classify and route documents | Green zone | Suggests type and destination | Corrects wrong suggestions | Track the accept rate |
| 3 | Match bank lines to ledger entries | Green zone | Proposes matches with reasons | Approves fuzzy matches | Exact matches by rule only |
| 4 | Draft standard replies | Green zone | Fills templates with system facts | Sends, then spot-checks | No invented dates or promises |
| 5 | Assemble reports and commentary | Green zone | Builds report, drafts description | Checks and decides | Control total equals the ledger |
| 6 | Flag duplicates and anomalies | Green zone | Flags only | Closes each flag with an outcome | Log outcomes, tune the rules |
| 7 | Route invoices for approval | Orange zone | Finds the approver, sends request | Approves or rejects | Approval matrix lives in the workflow |
| 8 | Prepare payment runs | Orange zone | Builds the batch | Releases payment at the bank | No release credentials for the agent |
| 9 | Draft forecasts | Orange zone | Builds a range from the data | Owns the assumptions | Backtest against actuals |
| 10 | Collections outreach | Orange zone | Drafts reminders by bucket | Chooses who, sends sensitive ones | Exclude disputes and unapplied payments |
| 11 | Propose journal entries | Orange zone | Drafts entry with source document | Reviews and posts | Balanced, sourced, open period |
| 12 | Verify vendor bank changes | Orange zone | Detects change, prepares request | Verifies on an independent channel | Hold payments until verified |
| 13 | Credit and lending decisions | Red zone | Summarizes and drafts a memo | Makes and explains the decision | Specific written reasons |
| 14 | Conclude something is fraud | Red zone | Assembles evidence | Investigates and decides | Flag, never verdict |
| 15 | Post entries and close periods | Red zone | Prepares and runs the checklist | Approves posting and lock | A named reviewer |
| 16 | File taxes and submissions | Red zone | Organizes workpapers | Reviews and signs | Qualified preparer signs |
| 17 | Change its own permissions or limits | Red zone | Requests a change | Approves in a place the agent cannot write | Limits are set outside the agent |
| 18 | Pay new payees or large sums alone | Red zone | Prepares and queues | Releases | Caps, log and kill switch if ever allowed |
Two things to notice. First, the same task family appears in more than one zone depending on the step: reports are green, acting on them is orange. Second, the map moves. As you collect evidence that a task is stable, a person-approved orange step can become a rule-checked green one. The only direction we would not move without very good reasons is toward red.
A spreadsheet that ranks your repetitive tasks by what is worth automating first. List the task, rate how often it happens, how long it takes, how error-prone it is and how many tools it touches, and the sheet orders your list. Enter your email below and we will send the download link.
Score your own tasks: worksheet and net-hours formula
Your finance work will not match the 18 tasks exactly. This section gives you a worksheet to sort your own, and a formula to check whether automating a task is worth it before you spend a week building it.
The sorting worksheet
For each task, answer the four questions from section 2 and apply the rules in order.
- Duty to explain: yes. Red, stop here.
- Checking takes as long as doing the task. Not yet. Improve the process first.
- Otherwise, add one point if the result is hard to undo, and one point if it moves money or changes a book of record.
- Score 0: green. Score 1 or 2: orange.
These tasks and answers are illustrative. Run your own through the same steps.
| Task | Duty to explain? | Hard to undo? | Moves money or books? | Result |
|---|---|---|---|---|
| Pull invoice totals into a draft sheet | No | No (0) | No (0) | Score 0: green |
| Email customers whose invoices are 30 days late | No | Yes (1) | No (0) | Score 1: orange |
| Approve a credit line for a new customer | Yes | n/a | n/a | Red |
The net-hours formula
Automation only saves time if the review and the exceptions cost less than the manual work they replace. Use these five inputs, all of which you can measure in an afternoon:
- V: items per month (invoices, reconciliation lines, reports).
- M: minutes to do one item by hand.
- R: minutes to review an item the agent handled.
- E: the share of items that become exceptions a person must handle (for example 0.15 for 15%).
- X: extra minutes an exception costs on top of doing it by hand, for triage and handoffs.
Net hours saved per month = V × [ M − (1 − E) × R − E × (M + X) ] ÷ 60
Multiply by your loaded hourly cost, then subtract tool and upkeep costs, to get a monthly figure.
Assume V = 400, M = 12 minutes, R = 2 minutes, X = 3 minutes, and a loaded cost of $30 per hour. Only the exception rate E changes. The numbers are invented to show how the formula behaves.
| Exception rate (E) | Net minutes saved per item | Net hours per month | Value at $30 per hour |
|---|---|---|---|
| 15% | 8.05 | 53.7 | about $1,610 |
| 50% | 3.50 | 23.3 | about $700 |
| 80% | -0.40 | -2.7 | a loss of about $80 |
The lesson is not the specific numbers. It is that the exception rate decides everything. At low exception rates the savings are large. As exceptions climb, they shrink fast, and at some point the agent costs you time. This is why a clean exception queue and a drift metric on exception rate (section 9) matter more than the model you pick.
How to build human-in-the-loop without killing productivity
"Keep a human in the loop" is the advice everyone gives and few people explain. Done badly, it means a person reads every item and the automation saves nothing. Done well, the person sees only the items that need judgment, with the evidence in front of them, and approves in seconds. These seven patterns are how you get the second version.
1. Confidence thresholds and routing
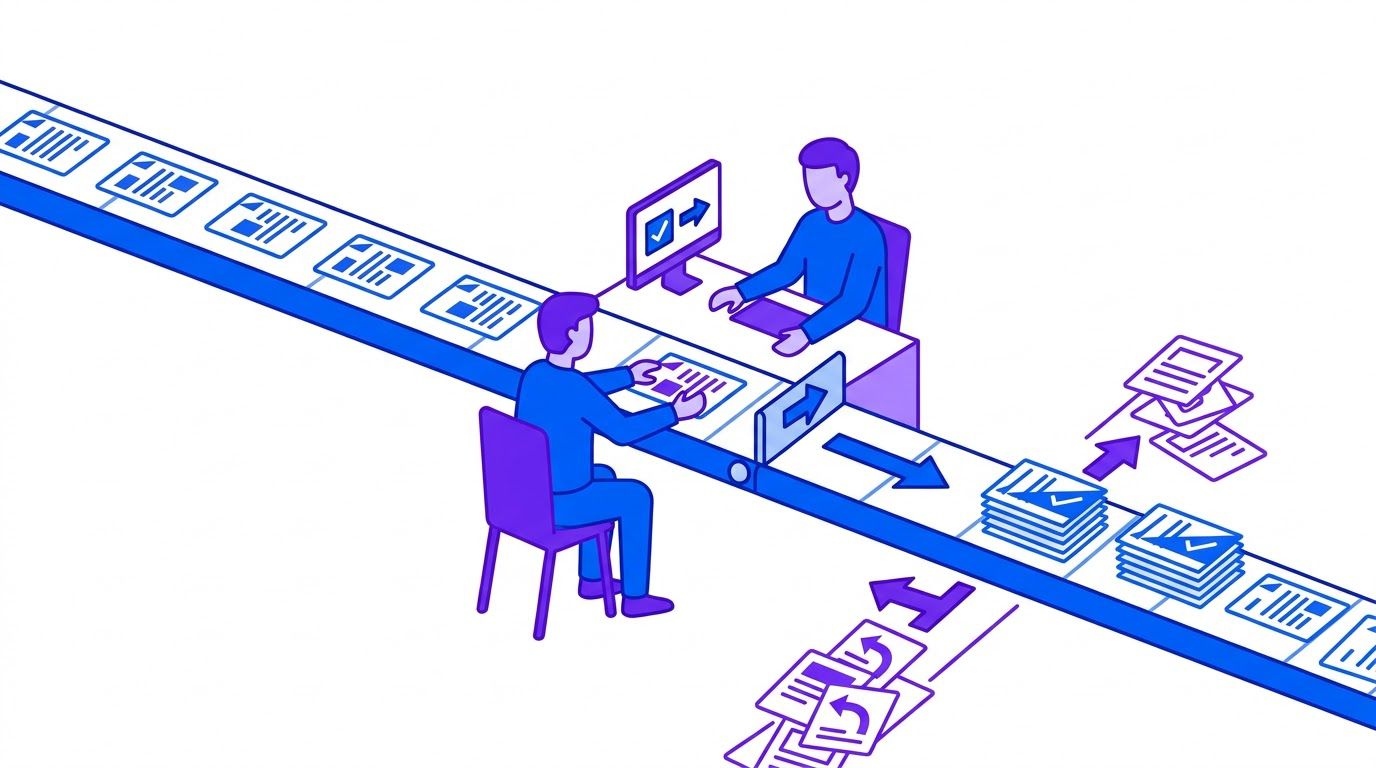
Have the agent report how sure it is about each field, and route by that score and by dollar value. High confidence and small amount: pass to the draft queue. Low confidence or large amount: send to review. The thresholds are yours to set, and you should set them conservatively at first and loosen them only as evidence builds.
2. An exception queue, not an inbox
Exceptions need a dedicated place with a status, an owner and an age. If they land in someone’s email, they are lost within a week. A simple shared table works: item, reason it was flagged, who has it, when it arrived, what happened. The age column matters most, because an exception that sits for days is a vendor waiting for payment.
3. Dollar caps and scoped credentials
Give the agent the narrowest access that lets it do its job. Read-only access to the accounting system for reporting tasks. Write access to a draft area, not the ledger, for extraction. No ability at all to release payments. Caps and scopes are controls that do not depend on the model behaving, which is exactly why they are worth more than any instruction in a prompt.
4. Maker-checker: two roles, always
The person or system that prepares an action should never be the one that approves it. In practice, that means the agent prepares and a person approves, and that the person who submitted an invoice cannot approve it. This old accounting principle (segregation of duties) is the single most useful idea to bring into agent design.
5. Shadow mode before going live
Run the agent alongside the manual process for a few weeks without letting its output count. Compare the two. Where the agent and the person disagree, find out who was right. This gives you a baseline error rate and a list of document types that trip it up, before any of it touches a real ledger.
6. Sampled review
Once the agent runs live, review a random sample of the items it passed automatically, not only the ones it flagged. The flagged items tell you how the agent handles things it doubts. The random sample tells you what it gets wrong while sure of itself, which is the dangerous case. Start with a large sample and reduce it as the error rate holds steady.
7. An audit trail and a kill switch
Log every action: what came in, what the agent returned, what rule fired, who approved. And build one obvious way to stop everything, such as a single switch that sends all items to manual review. You will probably never need it. The one time you do, you will be glad it exists.
If your team wants a shared language, the US National Institute of Standards and Technology published the AI Risk Management Framework (AI RMF 1.0) on January 26, 2023, as a voluntary framework. It organizes AI risk work into four functions: govern, map, measure and manage. NIST followed it with a Generative AI Profile (NIST AI 600-1) on July 26, 2024. Neither is a legal requirement for a small business, but both are useful checklists when you need to explain your controls to a lender, a client or an auditor.
What this looks like as a workflow
Here is the invoice intake pattern, written as the steps a workflow tool such as n8n would run. Each step is visible, and each one is a place you can read, test and change.
- Trigger. A new invoice arrives in a mailbox or a shared folder.
- Extract. An AI step reads the document and returns structured fields, each with a confidence score.
- Validate by rules. Do the lines add up? Does the vendor exist? Is the date plausible? Fail any check and the item goes to the exception queue.
- Check for duplicates. Compare vendor, number and amount against what you have already seen.
- Route by threshold. Small and confident items go to the draft queue. Large, low-confidence or new-vendor items go to a person.
- Wait for a human. The workflow pauses and asks the right approver to approve or reject, then continues on their answer.
- Write a draft. The approved item is written to your accounting tool as a draft, never as a posted entry.
- Log. Every step, score and decision is recorded.
Nothing in that list needs the model to be perfect. It needs the rules to be strict and the person to be asked at the right moment. If you want to read a real example of the first half, our Extract Invoice Data from PDFs with n8n and Claude article is a good start. For the reporting side, see the Weekly Accounts Receivable Aging Report. You can import either and adapt it, and everything in our free workflows library is there to be read and reused.
When your setup does not match the examples, which is normal, adapting a workflow to your tools, your approval rules and your documents is the kind of work we do on request. The Request a Custom Workflow page takes a description of the task and returns a quote, so you can see the cost before you commit to anything.
Signals that a finance agent is drifting
An agent that worked well in March can work worse in September without anyone changing it. Vendors change their invoice layout, a new product line adds unfamiliar items, your accounting tool updates its fields, or the model behind the agent is updated by its provider. Drift is the slow slide in quality that follows. You catch it with a small set of numbers reviewed on a schedule, not by waiting for a complaint.
Measure these before you go live so that you have a baseline. The "what drift looks like" column gives illustrative patterns, not thresholds. Set your own alert levels once you have a few weeks of data.
| Metric | How to compute it | What drift can look like |
|---|---|---|
| Sampled field accuracy | Each week, check a random sample of auto-passed items against the source document | Accuracy slowly falling across consecutive weeks |
| Exception rate | Items sent to the exception queue divided by items processed | A steady climb, or a sudden jump after a vendor changes its format |
| Override rate | How often a person changes the agent’s suggestion | People correcting the same kind of field again and again |
| Review time per item | Average minutes a person spends on a reviewed item | Reviews taking longer, which often means the evidence shown is not enough |
| Confidence distribution | The spread of confidence scores across all items | Scores bunching near the top while accuracy falls: the agent is sure and wrong |
| Flag false-alarm rate | Closed flags marked as false alarms divided by all closed flags | Very high, so people stop reading flags, or suddenly low, so the rule may have stopped firing |
| Exception age | Days from arrival to resolution in the exception queue | Items piling up and aging, a sign of an unowned process |
| Cost per item | Model and tool costs divided by items processed | Cost rising with no change in volume, for example from retries or longer inputs |
What to do when a signal moves
- Tighten first. Lower the confidence threshold for automatic passing, or switch to reviewing everything, until you understand the cause.
- Compare to the baseline. Pull a sample from before and after the change and look at what differs.
- Find the change. New vendor format, new document type, a prompt edit, an update to the underlying model, a change in an upstream system.
- Fix and retest. Correct the cause, then run the shadow comparison again before loosening the thresholds.
- Write it down. A short log of what drifted and why is how you avoid learning the same lesson twice.
If you only look at what went wrong this week, you see the failures that were big enough to notice. Drift is made of failures that were each small enough to ignore. A line chart of five or six numbers, reviewed weekly, catches it earlier than any amount of vigilance.
What to automate first: a 30-day sequence
If you take one thing from this guide, make it this: start with one green task, and treat the first thirty days as a measurement exercise, not a launch. A plan like this works for most small finance teams.
- Week 1: choose and baseline. Pick the green task with the highest volume and the clearest definition of done, such as invoice data extraction or a weekly report. Time yourself doing it by hand and write down M, V and the types of exceptions you see.
- Week 2: shadow mode. Run the automation next to the manual process. Compare outputs every day. List every disagreement and who was right.
- Week 3: live with full review. Let the output count, but have a person review everything. Track the override rate and the review time.
- Week 4: sample and decide. Move to sampled review if the numbers hold. Calculate your net hours with the formula from section 7. If the savings are real, keep the task and add the drift metrics to your weekly routine. If not, fix the exceptions before expanding.
Only after a green task is stable for a few weeks should you consider an orange one, and then start with the orange task closest to the work you already automated. For most teams, that means invoice approval routing after extraction, or collections drafts after the aging report. Leave the red zone to people.
A final rule of thumb for choosing between two candidates: pick the one where you can explain the exception path out loud in one minute. If you cannot say where the weird documents go, the task is not ready.
When it is time to hand it to someone
Plenty of small teams will read this guide and build their first green workflow themselves, and that is a good outcome. The harder part tends to arrive a few weeks later: the approval rules need to match how your company really works, the exceptions need a proper queue, and the checks need to live in the workflow instead of in someone’s head.
That is where LeenLabs comes in. We build custom n8n workflows and adapt existing ones to your tools and rules. A request works like this:
- You send a short form describing the task, the tools involved, how many items you handle and where a person must approve.
- We read it and send you a quote. You see the cost before anything starts.
- You approve the quote and pay 40% to start.
- We build the workflow and deliver it. You pay the remaining 60% on delivery.
If you have hired freelancers on a marketplace before, you know the usual route: write a job post, collect proposals, interview candidates and then manage the build yourself. That route works well when you already know exactly what to ask for. Finance automation is harder to specify, because the risky part is not the code. It is the decisions: what the workflow may do alone, what needs approval, what happens to an exception. A structured request puts those questions up front, so the quote you receive is for a workflow with the controls in this guide built in, rather than for a script you then have to supervise.
Every workflow we build is an n8n workflow, which means every step, branch and approval point is visible. You can open it and see what it does, which is the point.
Pick a task from the boundary map, describe it in the form and tell us where a person must approve. We will send back a quote to build it as a custom n8n workflow, or to adapt an existing one to your setup.
Not ready for a request? Start with the free workflows, download the Scorecard from the form above to rank your tasks, and come back when you have your top candidate.
Frequently asked questions
Can AI agents do bookkeeping on their own in 2026?
Parts of it, yes. Reading documents, suggesting categories, proposing reconciliation matches and building reports are reliable with light checks. Posting entries, closing periods and filing returns still need a person who can explain and sign. A well-designed setup lets the agent prepare most of the work while a person approves the steps that matter.
Is it safe to let an AI agent pay invoices?
Not as a default. Preparing a payment batch is a good job for an agent, and releasing the payment should stay with a person who has bank authority. If a team ever allows autonomous payments, it should be for small, recurring, pre-approved payees under a hard cap, with a log and a way to stop everything. That is a deliberate decision, not a starting point.
What is the difference between an AI agent and an automation workflow?
A workflow follows steps you defined, and an agent decides some of its own steps. In finance, the best designs mix them: a workflow with fixed rules and approval points, and an AI step only where the input is messy, such as reading a crooked invoice. Fixed rules are easier to audit and cheaper to run, so use them wherever the logic is clear.
How do I know if my finance agent is making mistakes?
Sample its output every week against the source documents, and track a few trend metrics: exception rate, override rate, confidence distribution and review time. Section 9 lists eight. A single metric can mislead you, but a trend across several usually shows a problem before a customer or a vendor does.
Do I have to explain AI-assisted credit decisions to applicants?
If you extend credit, rules such as Regulation B in the United States require adverse action notices that state the specific principal reasons for a refusal, within set time limits, and a generic reference to a score is not enough under the regulation’s text. Whether those rules apply to your situation, including some business credit, is a question for a lawyer. This guide is general information, not legal advice.
What should I automate first in accounts payable?
Start with invoice data extraction, with arithmetic and duplicate checks behind it, writing to a draft queue. It is high-volume, easy to verify and easy to reverse. Add approval routing next, and leave payment release with a person.
How much human review is enough?
There is no universal number. Start by reviewing everything while you measure the error rate. Once the rate is stable and low, move to reviewing flagged items plus a random sample of what passed. Keep a larger sample for anything that touches money, and lower it only when your own data supports it.
Is it safe to send financial documents to an AI model?
It depends on the provider’s terms and on what you send. Read the data-handling and retention terms for any service you use, send only the fields the task needs, and consider redacting account numbers and personal data before the AI step. If your documents include regulated or sensitive data, check with your legal or security advisor first.
Sources and how we checked them
Every figure in this guide was read on the source page on October 31, 2026. The worked examples, tables and thresholds are illustrations and are not drawn from any source.
- FirstPageSage, Agentic AI Adoption Statistics: SMB adoption (13%), stage distribution (79% experimenting), SMB abandonment (43%). Page updated October 6, 2026.
- Retool, AI Governance Report 2026: 307 senior technology and security leaders surveyed in May 2026; 22% with a production incident from an AI-generated internal tool; 8% with strong governance. Published June 17, 2026.
- Forrester, The State of Agentic AI in 2026: Companies Are Chasing, Few Are Catching: published June 3, 2026.
- eCFR, 12 CFR 1002.9 (Regulation B, Notifications): the 30-day notice and specific-reasons requirements.
- CFPB, Consumer Financial Protection Circular 2022-03 and the CFPB’s withdrawn guidance list, which shows the circular withdrawn on May 12, 2025.
- NIST, AI Risk Management Framework: AI RMF 1.0 released January 26, 2023. NIST AI 600-1, Generative AI Profile: July 26, 2024.
- About Us: who we are and how we work
- Free Workflows: n8n workflows with JSON you can import
- Request a Custom Workflow: describe a task and get a quote
- Terms of Service
- Privacy Policy
This article is general information and not legal, tax or financial advice. Laws and rules differ by country and state and change over time. Check with a qualified professional about your own situation.